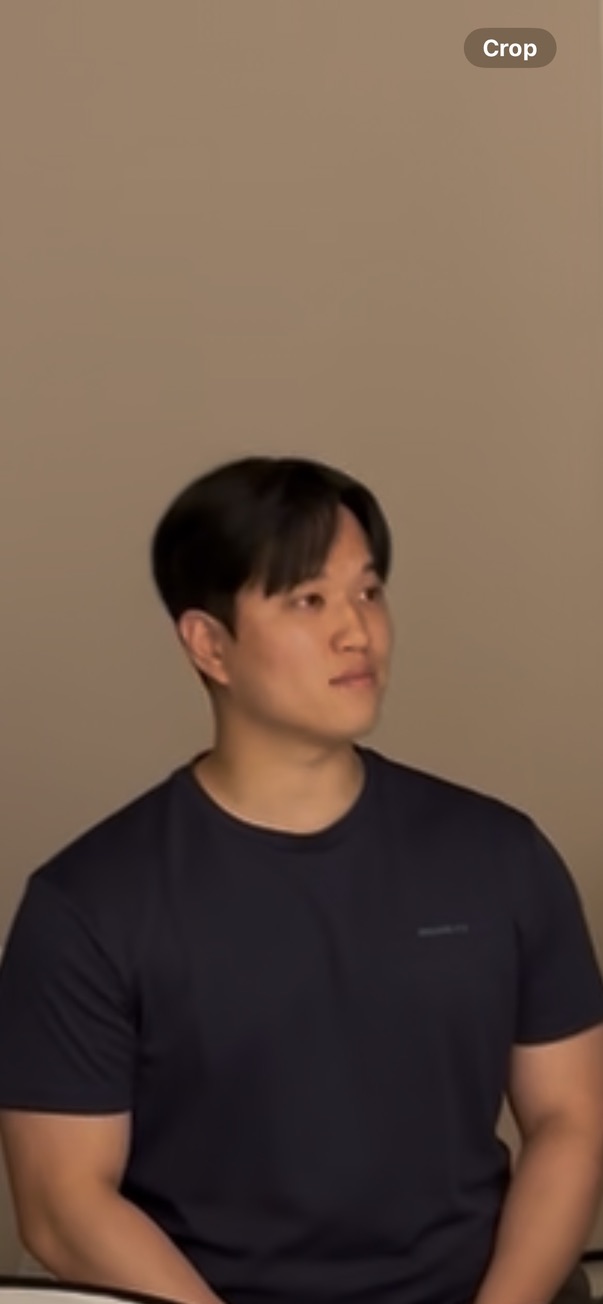
I am a Research Collaborator at the KAIST STAI Lab under Professor Seong Joon Oh, and a Research Fellow at the SPAR Research Fellowship, researching how reinforcement learning affects metacognition in LLMs using mechanistic interpretability methods.
Previously, I was a Research Engineer at Arcadia Impact working on Automated Research Alignment, a Research Fellow at the MARS V Fellowship investigating mechanistic detection of semantically unfaithful LLM translations of formal specifications, and an AI Engineer at Scale AI building multi-agent deep research systems. Before that, I was a software engineer at Two Sigma and Amazon.
I am interested in AI safety, mechanistic interpretability, and alignment research.
Publications
Neighbor Crowding Predicts Feature Stability in Sparse Autoencoders
Game-Theoretic Specialization of Safety LoRA Adapters
Representational Adversarial Steganography in Colluding LLMs
Chain-of-thought Faithfulness in Small Reasoning Models
Research
KAIST STAI Lab, Research Collaborator
SPAR Research Fellowship, Research Fellow
Arcadia Impact, Research Engineer
MARS V Fellowship, Research Fellow
Medical Inhaler Spacer Research
Experience
Scale AI, AI Engineer
Two Sigma, Software Engineer
Amazon, Software Development Engineer
Education
University of Southern California, M.S. Computer Science
University of Southern California, B.S. Mechanical Engineering